Pose6DAug: Physically Plausible Multi-view Object
Swapping for Robot Data Augmentation

1KAIST    2Korea University    3RLWRLD
*Equal contribution    †Corresponding author
NeurIPS 2026

Given a successful episode, Pose6DAug swaps only the manipulated object in 3D, which preserves the original action trajectory, grasp contact, and cross-view geometry. This enables synthesizing new, physically grounded demonstrations.

Before
Original successful episode (source object)
After
Augmented episode (target object swapped in 3D)
Real robot
Real Franka teleoperation on the calibrated rig: original episode (left), Pose6DAug with the spray bottle swapped in and following the real gripper (middle), VACE (right). Estimated pose, predicted mask, reconstructed mesh.

Abstract

Vision-language-action (VLA) policies have shown strong potential for general-purpose manipulation, yet they often fail on novel, out-of-distribution objects whose appearance or geometry deviates from the training distribution. The standard remedy is to collect multi-view teleoperation data for every failure case, but this scales poorly in both cost and time. We introduce Pose6DAug, a failure-driven data augmentation framework that turns a policy's own successful episodes into targeted demonstrations for its failure modes, without any new data collection. Our key insight is that each successful episode already encodes a physically valid action trajectory together with calibrated multi-view observations. By swapping only the manipulated object while preserving this trajectory, we obtain new and physically grounded demonstrations. However, naive 2D video editing breaks multi-view consistency and physical plausibility, particularly under heavy occlusion and egocentric viewpoints. Our method instead operates directly in 3D, anchoring the target object with an explicit mesh driven by a temporally coherent 6D pose trajectory, ensuring geometrically consistent renderings across all camera views. Fine-tuning a VLA on data augmented by our method improves success rates by 16.5% relative to the state-of-the-art baseline on novel objects, while preserving in-distribution performance.

Method

Pose6DAug overview
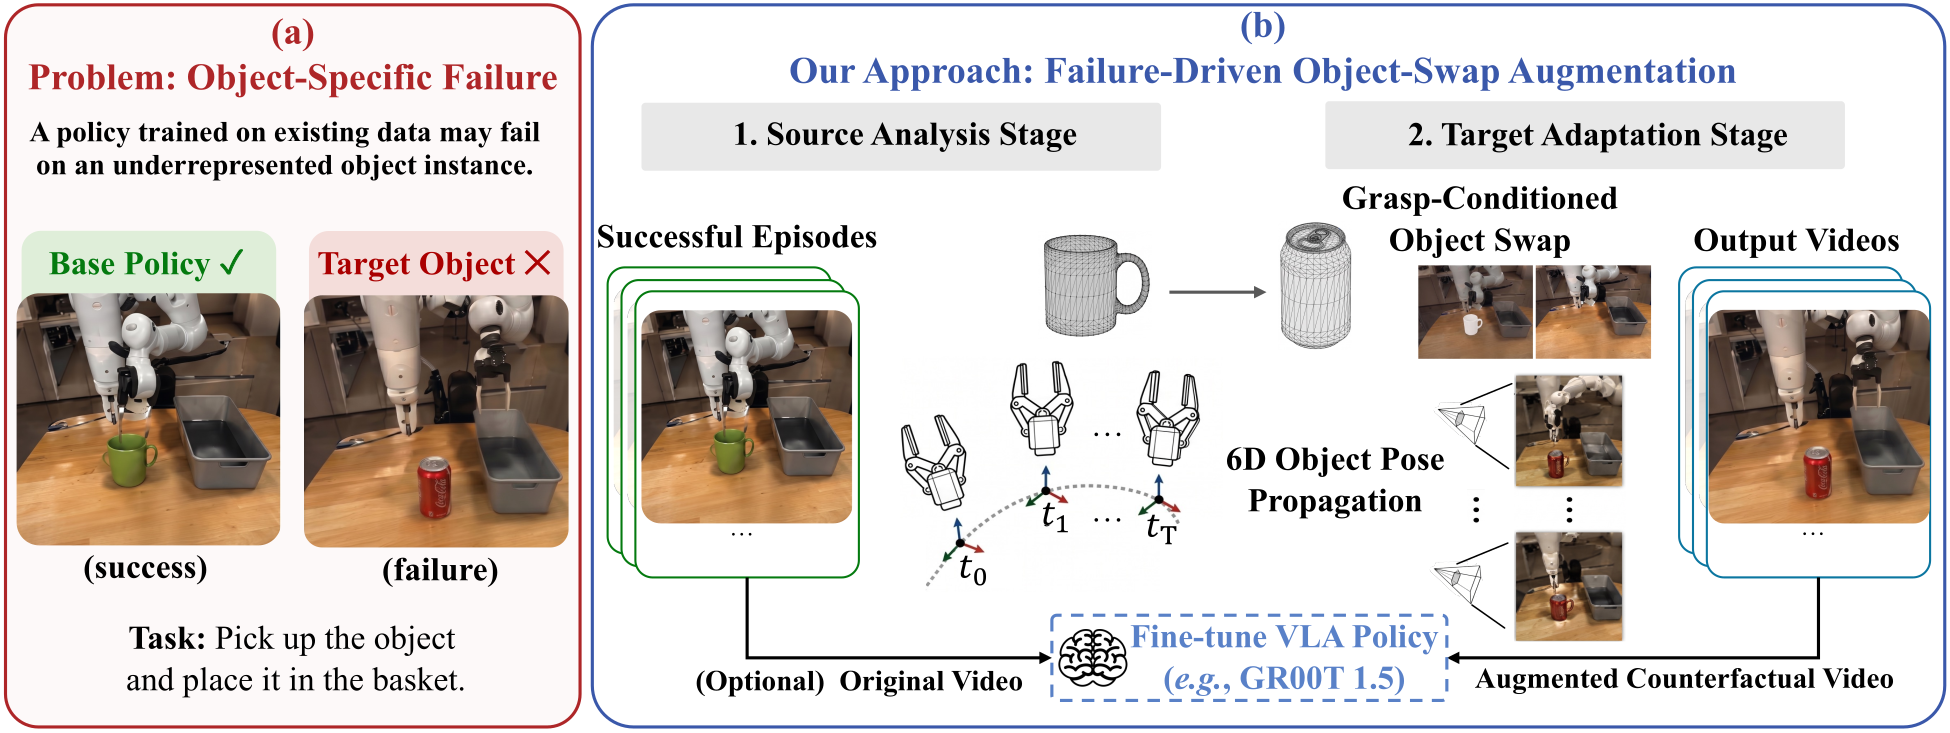
Failure-driven object-swap augmentation. From a policy's failures on novel objects, we retrieve successful in-distribution episodes and, preserving their action trajectory, replace the manipulated object with the target object via a 3D mesh driven by a 6D pose sequence under rigid coupling — rendering physically plausible, multi-view-consistent videos for fine-tuning.

Our pipeline decomposes object-centric augmentation into three stages: (1) target mesh reconstruction and 6D pose extraction, (2) object augmentation (rotation, translation along the approach axis, and rescaling), and (3) 3D mesh-pose guided video composition. Because every camera renders the same 3D mesh at a shared world-frame pose, multi-view consistency holds by construction — in contrast to per-view 2D editing, which introduces cross-camera discrepancies.

Augmentation details
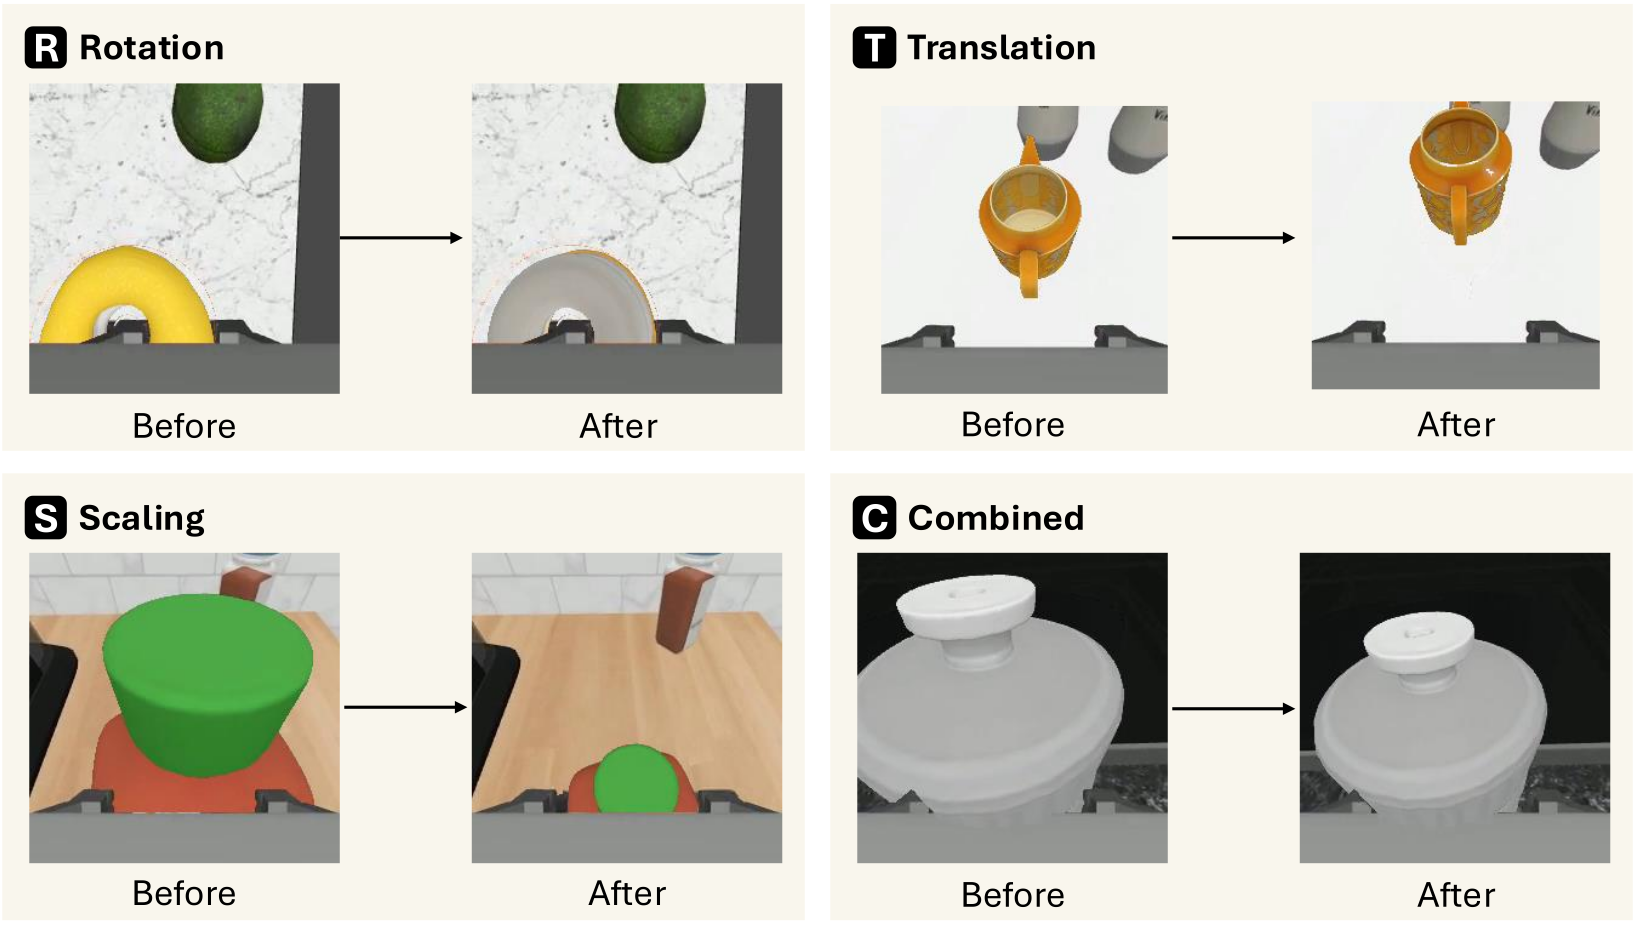
Augmentation details. Combinations of rotation, flipping, translation, and vertical rescaling keep the swapped mesh within a graspable range of the gripper, ensuring physically plausible contact after substitution.

Quantitative Results

Base model: GR00T-1.5 on the RoboCasa365 Counter-to-Cabinet task.

Table 1. Performance on failure episodes (instances the base policy never solved). Success Rate (%) and Turnover Ratio (%), split into in-distribution (ID) and out-of-distribution (OOD); averaged over 3 seeds. Higher is better.
MethodPropertiesSuccess Rate (%)Turnover Ratio (%)
Multi-viewSim-freeIDOODAvg.IDOODAvg.
Base Policy––0.00.00.00.00.00.0
MimicGen✓✗14.717.315.816.418.117.2
VACE✗✓12.821.216.414.922.418.2
Pose6DAug (Ours)✓✓21.224.722.824.624.224.5
Table 2. Augmentation-only training on the 8 hardest unseen objects (20 episodes each). Trained purely on synthesized demonstrations; class recovery = at least one success per instance.
MethodSuccess RateObjects Recovered
Base Policy15/160 (9.4%)–
MimicGen9/160 (5.7%)2 / 8
VACE24/160 (15.0%)5 / 8
Pose6DAug (Ours)34/160 (21.2%)7 / 8

Real-World Experiments

Pose6DAug is not limited to simulation. In the real world the pipeline consumes camera parameters, object masks, an object mesh and a 6D pose trajectory that are all estimated rather than read from a simulator: camera parameters from standard stereo calibration (OpenCV), masks from an off-the-shelf segmentation model, meshes from a 3D generator, and an initial object pose from an RGB-D pose estimator refined with the mask and point-to-point ICP on stereo depth. Every input therefore has a real-world counterpart.

Tracking the source object through the video needs no continuous 6D tracker, the stage most exposed to occlusion and estimator error. Before the grasp the object rests on the table, so gravity fixes its pose and constrains its orientation to the surface normal; after the grasp it is transported by the parallel jaws, so it follows the gripper under the recorded relative end-effector transform. Propagating the initial pose this way guarantees that the rendered object follows the gripper faithfully.

Setup. Tabletop pick-and-place: the robot moves an object from the table into a basket. Objects: a Bref spray bottle, a snack box, an aluminum can and a keyring-sized deformable doll. Hardware: a Robotiq 2F-85 parallel-jaw gripper on a Franka Emika Panda 7-DoF arm, identical to the DROID setup. We compare against VACE; MimicGen requires simulator rollouts and is not applicable to real data. We report the overall success rate and, per object, whether the augmentation recovers episodes the base policy failed.

Table 3. Real-world results (Franka Panda + Robotiq 2F-85, table-to-basket pick-and-place). Success rate and per-object recovery of previously failed episodes.
Base PolicyVACEPose6DAug (Ours)
Success Rate10.0%8.3%25.0%
Bref Spray–✓✓
Snack Box–✓✓
Aluminum Can–✗✓
Doll–✗✓

Pose6DAug more than doubles the base policy and recovers all four objects under estimated poses, predicted masks and reconstructed meshes. VACE does not improve over the base policy, so the gain does not follow from generative editing in general but from the mesh-grounded augmentation. This is the noisy-perception regime, and the effect observed in simulation carries over to it.

Real-world augmentation: Original → Pose6DAug → VACE

Spray-bottle episode on the calibrated rig. Left: original teleoperation; middle: Pose6DAug, the reconstructed mesh swapped in and following the real gripper; right: VACE. Clips end before the release.

Exocentric camera
Wrist camera

More real-world swaps: Original → Pose6DAug → VACE

Kanu box → ABC chocolate box (exocentric camera)
Orange aluminum can → green aluminum can (exocentric camera)

Comparison with VACE: laundry-room episode

VACE
Pose6DAug
Laundry-room episode: VACE edit vs. Pose6DAug swap
Qualitative Results

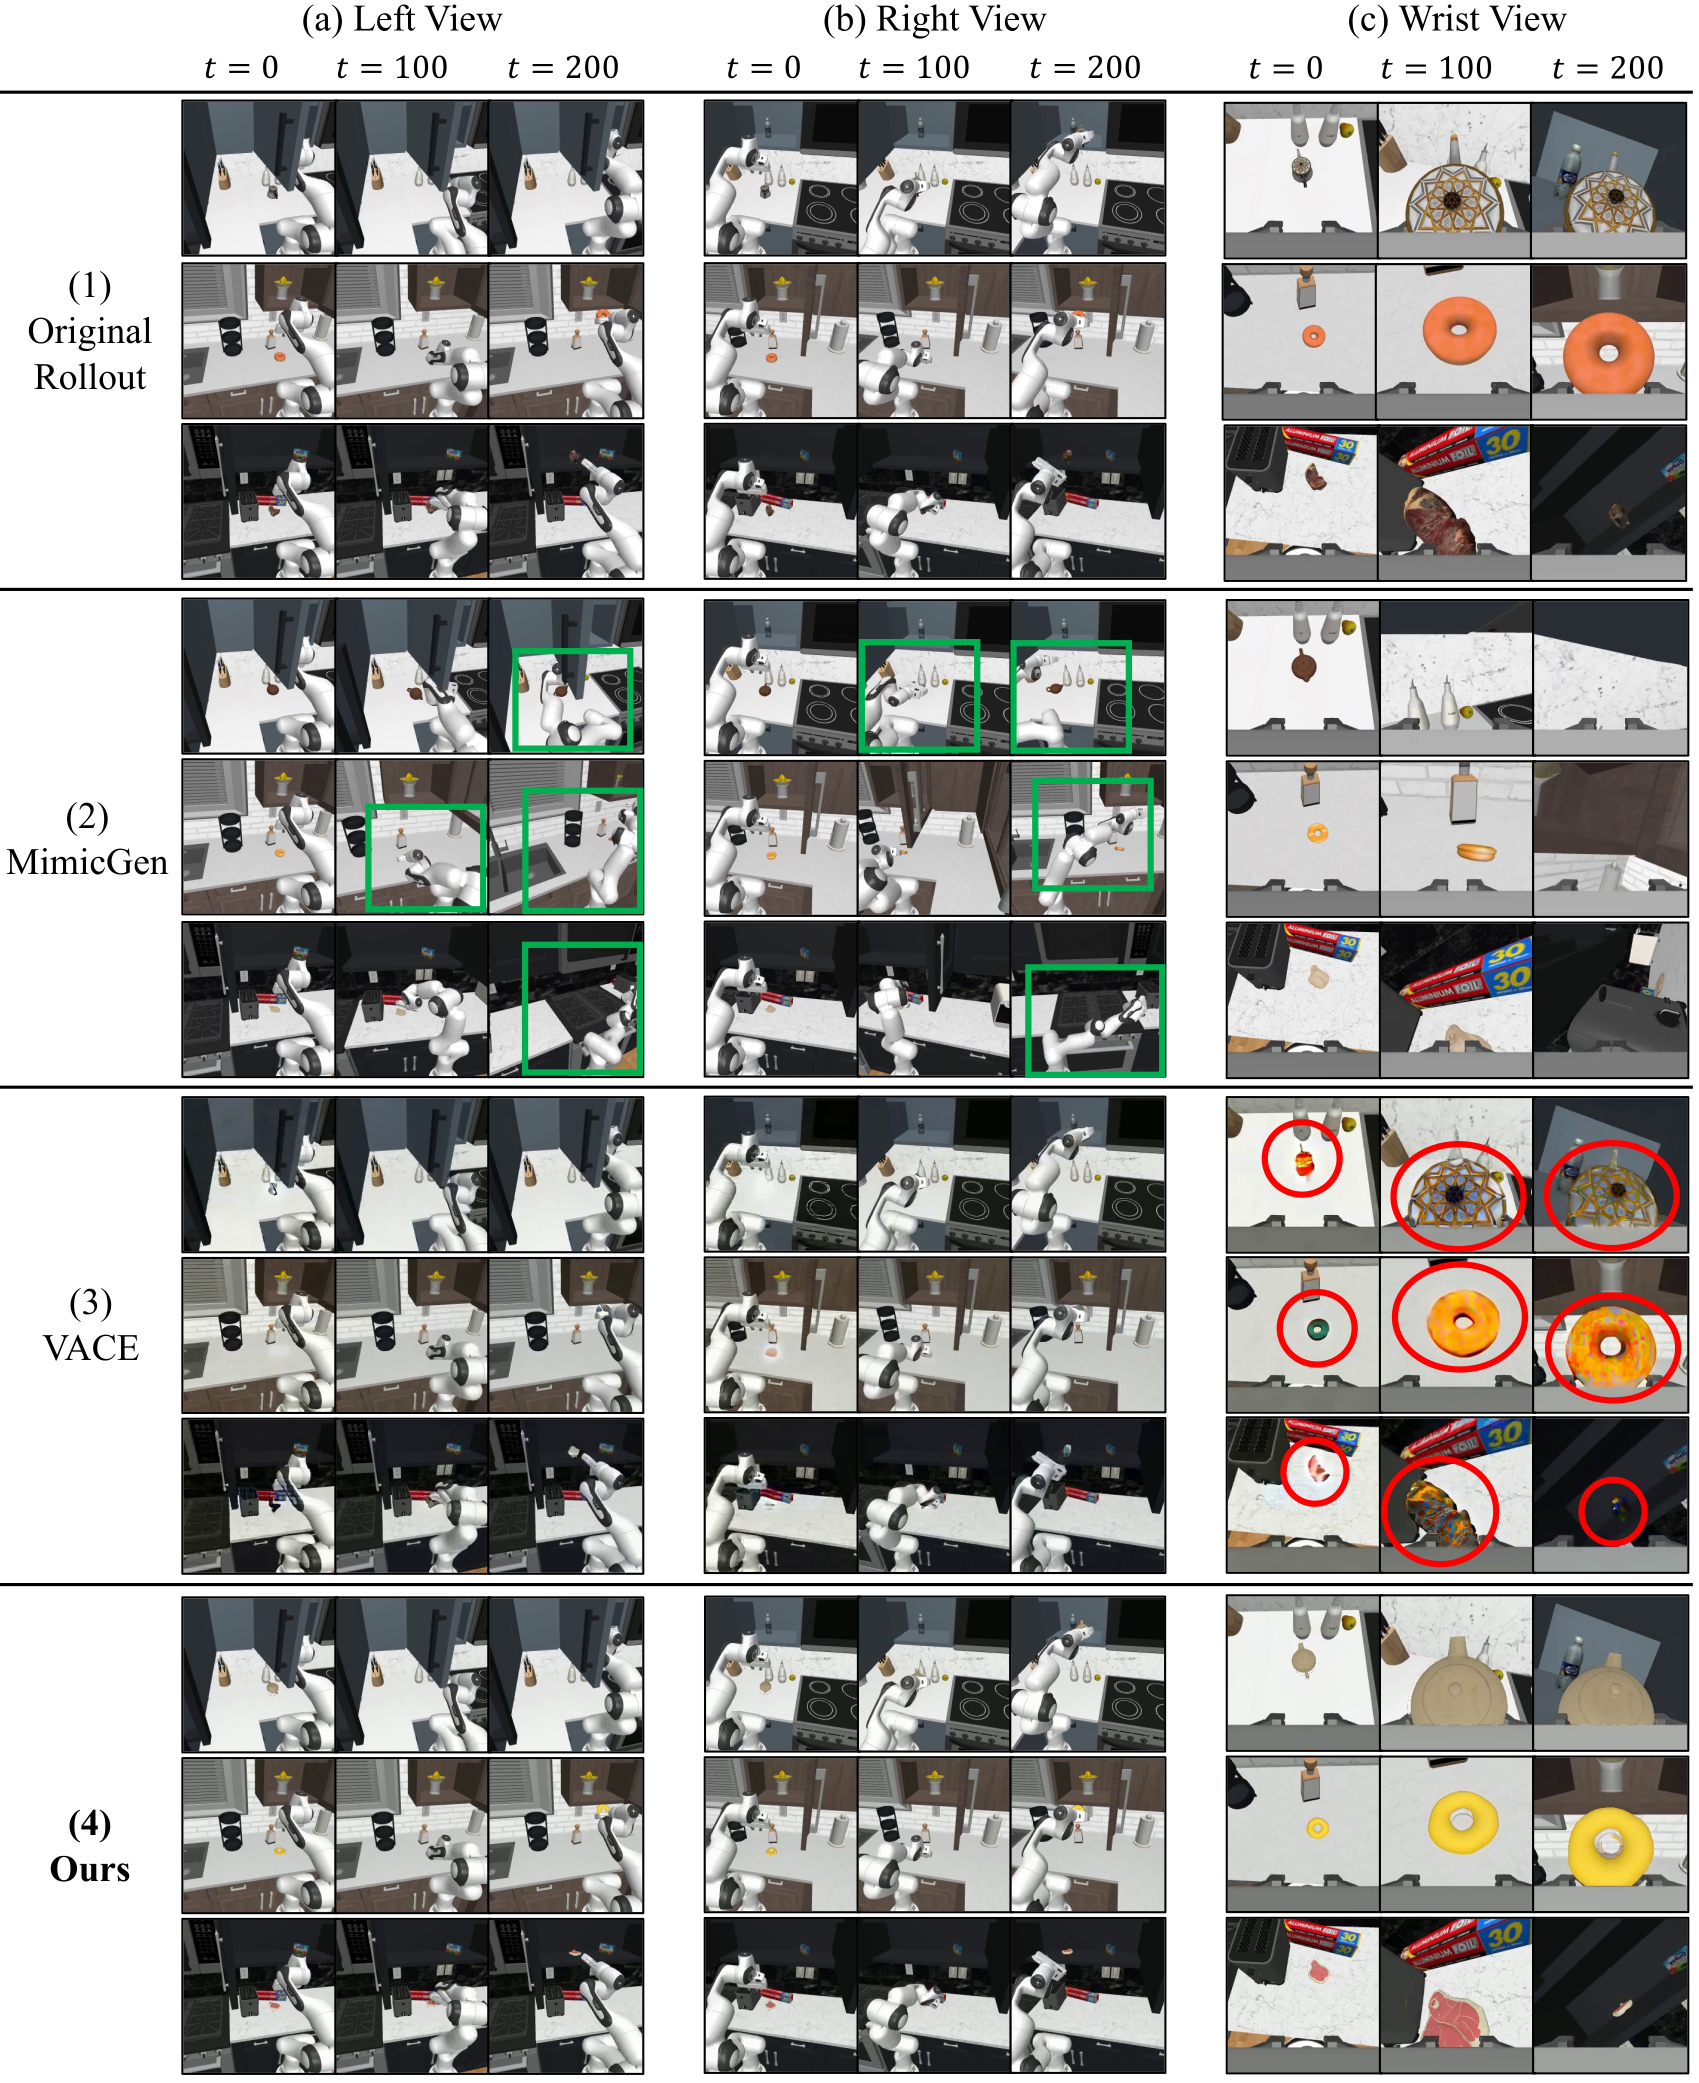
Object-swap augmentations in simulation (left, right and wrist views)

Source episodes from RoboCasa365 Counter-to-Cabinet, re-rendered with one of the eight hardest unseen objects; the action trajectory is the source demonstration's, adapted only at the grasp.

Mango → Teapot
Cream cheese stick → Steak
Sweet potato → Donut
Honey bottle → Soap dispenser
Qualitative comparison across views
Qualitative comparison across left/right (exocentric) and wrist (egocentric) views. Red circles mark multi-view inconsistencies; green rectangles mark physically implausible trajectories. Pose6DAug stays consistent across all views.

BibTeX

@inproceedings{lee2026pose6daug,
  title   = {Pose6DAug: Physically Plausible Multi-view Object Swapping
             for Robot Data Augmentation},
  author  = {Lee, Jonghoon and Park, Seong Hyeon and Jeon, Byungwoo
             and Lee, Minha and Shin, Jinwoo},
  booktitle = {Advances in Neural Information Processing Systems (NeurIPS)},
  year      = {2026},
  note      = {arXiv:2606.20118}
}